Orchids
An identification model, a GAN, a hybrid visualizer, and 170 years of Cattleya hybrid registrations.
Demo · Model · Code · Hybrid visualizer
Orchids have over 30,000 species, and photos of them online are uneven. A few cultivated genera have most of the images, many tropical species have only a handful, and labels are often slightly wrong: the right genus with the wrong species, old synonyms, cultivar names. Most of my time on this went into cleaning data.
Identification: orchid-clip-v8
A fine-tune of BioCLIP 2 (ViT-L/14) on 1.14M photos of 5,124 species. Rare species were sampled more often (weight ∝ 1/√n), names were mapped to accepted species in WCVP, and images that scored badly against their own label were dropped.
| model | top-1 per image | top-1 per genus | top-5 |
|---|---|---|---|
| BioCLIP 2 | 0.873 | 0.768 | 0.978 |
| orchid-clip-v8 | 0.911 | 0.844 | 0.986 |
The holdout is 4,000 images from a hash-partitioned 2% bucket. It is mostly Ophrys, so the per-genus column (14 genera, each weighted equally) is the fairer comparison. Gains were largest on small genera such as Lepanthes and Stelis. It is a closed-set test against the 547 species in the holdout, and 320 of the 355 errors are between species of the same genus.
The demo ranks a photo against 25,083 species, so species accuracy there is lower: on 8,837 photos held out of training, species top-1 is 0.69 and genus top-1 is 0.92. It names a species only when the top two scores are far enough apart, and otherwise gives just the genus. The cutoff was tuned and scored on those same photos (named species right 90% of the time, a name given for 55% of photos), so those two numbers are optimistic. For species with no reference images in the demo, genus top-1 is about 0.55. It works best on field photos, and much worse on herbarium sheets and illustrations.
Until October 2026 the demo was missing about 5,200 species in the tribes Vandeae and Cymbidieae, including Phalaenopsis, Vanda, Oncidium and Cymbidium. The build step filtered by subfamily and left out the older name Vandoideae, which those species carry in the source data, so photos of them could only match some other genus. Adding them raised held-out genus top-1 from 0.80 to 0.92.
OrchidGAN
My first orchid model: StyleGAN2-ADA, starting from weights pretrained on a public flowers dataset and fine-tuned on curated Cattleya photos. It makes plausible blooms, but it has no idea which orchid it drew, which is what led to the identification model. The training images are not redistributed.
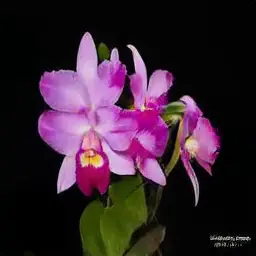
Cattleya hybrid visualizer
A Cattleya cross takes four to seven years to flower. The visualizer shows what 27 registered crosses might look like. A rule-based phenotype engine blends the parents’ traits (pigment channels handled separately, dominance rules, recessive traits allowed through more in later generations) into a short prompt for SDXL with an ancestry LoRA. The engine covers 119 species, and its rules are heuristics. Every image is a prediction, not a photograph.

Across 1,002 registered hybrids, a real hybrid’s orchid-clip-v8 embedding sits closer to its parents’ midpoint than a shuffled null (cosine 0.910 vs 0.730), and this replicates on an independent backbone (DINOv2: 0.886 vs 0.539). Hybrids also sit off the line between their parents, and further off when the parents look more different (Spearman ρ 0.52, n = 485, permutation p < 0.001; 0.65 on DINOv2). This is visual similarity, not genetics. Weighting the blend by the dominance rules did not beat the plain midpoint.
Code: orchid-clip · orchid-hybrid-visualizer
Cattleya hybridization over time
A course project (2025) on about 18,700 registered Cattleya hybrids from the RHS register, as republished on OrchidRoots. Nineteenth-century crosses were mostly species × species. Hybrid × hybrid crosses rose through the corsage era, peaked around 1960, then fell steeply, and the three kinds of cross are closer to an even mix today. Mean ancestors per hybrid rose from about 2 to about 22 by the 1970s and has stayed there since.

The number of hybrids a species has produced is clustered on the phylogeny, but only a species-level tree shows it: Pagel’s λ, Moran’s I and Abouheif’s Cmean are significant there, and nothing is significant on a tree of subgeneric ranks. Blomberg’s K is not significant on either.
Code and write-up: cattleya-hybridization